Giovanbattista Gravina
About
Robotics researcher currently pursuing a PhD at the Humanoids and Human-Centered Mechatronics Lab (HHCM), Italian Institute of Technology, Genova, Italy.
Working on robot control for legged systems, focusing on reinforcement learning to address locomotion and loco-manipulation tasks.
M.Sc. in Artificial Intelligence and Robotics from Sapienza University of Rome (2024) and B.Sc. in Electronic and Computer Engineering from the University of Campania “Luigi Vanvitelli” (2021), both cum laude.
News
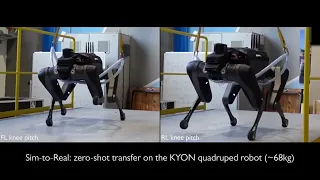
- [Sep. 2026] Presented our paper “Learning Fault-Tolerant Locomotion with Adaptive Gait Timing” as an oral presentation at IROS 2026 in Pittsburgh, USA.
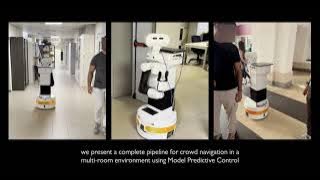
- [Jul. 2026] Our paper on crowd navigation in multi-room environments is published in Frontiers in Robotics and AI.
- [Jun. 2026] Our paper on fault-tolerant locomotion is accepted to IROS 2026.
Selected Publications
-
 IROS
IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2026.
-
 Frontiers
 in Robotics and AI, Special Issue on “Social Robot Navigation – Opportunities, Algorithms, Tools, and Systems”, 2026.
Selected Projects
-
Multi-Skill DistillationUnifying multiple behaviors in a single policy via multi-expert distillation, coupling reinforcement learning and imitation learning. Applied to fall recovery and locomotion under joint failures for a quadruped, the policy autonomously selects the appropriate skill (getting up, quadrupedal or bipedal locomotion) by implicitly reconstructing the failure condition from proprioception only, without fault information or skill selection.
Powered by Jekyll and the Minimal Light theme.